Four renders of the same poster. Same prompt, same seed, same model. The client approved one of them. An AI judge, asked which one followed the brief, picked a different one. Both were right, and the gap between them is the most useful thing the experiment produced.
What Is the Eval Flywheel?
At LangChain’s Interrupt conference in London this week, Harrison Chase described how agents get better over time: run the agent, collect feedback, inspect the trace, add the failure to your eval set, then change the model, the harness, or the context. Repeat. It is a flywheel, and most of the conversation about it is about text agents: support bots, coding assistants, research tools.
We wanted to know whether the same loop works for generative media, where “the trace” is a ComfyUI graph and “feedback” is an art director squinting at a poster. So we ran it, once, on real assets, using nothing but Numonic’s experiment tools over MCP.
The Setup
The material already existed. On October 15 we rendered four versions of a short-film poster with Flux dev: a red-and-white lighthouse on a basalt cliff, its beam cutting through sea fog, a figure in a yellow raincoat, and room at the top for a title. Every render used seed 41187, 28 steps and the same prompt. The only thing that changed was Flux guidance: 2.5, 3.0, 3.5, and 4.0.
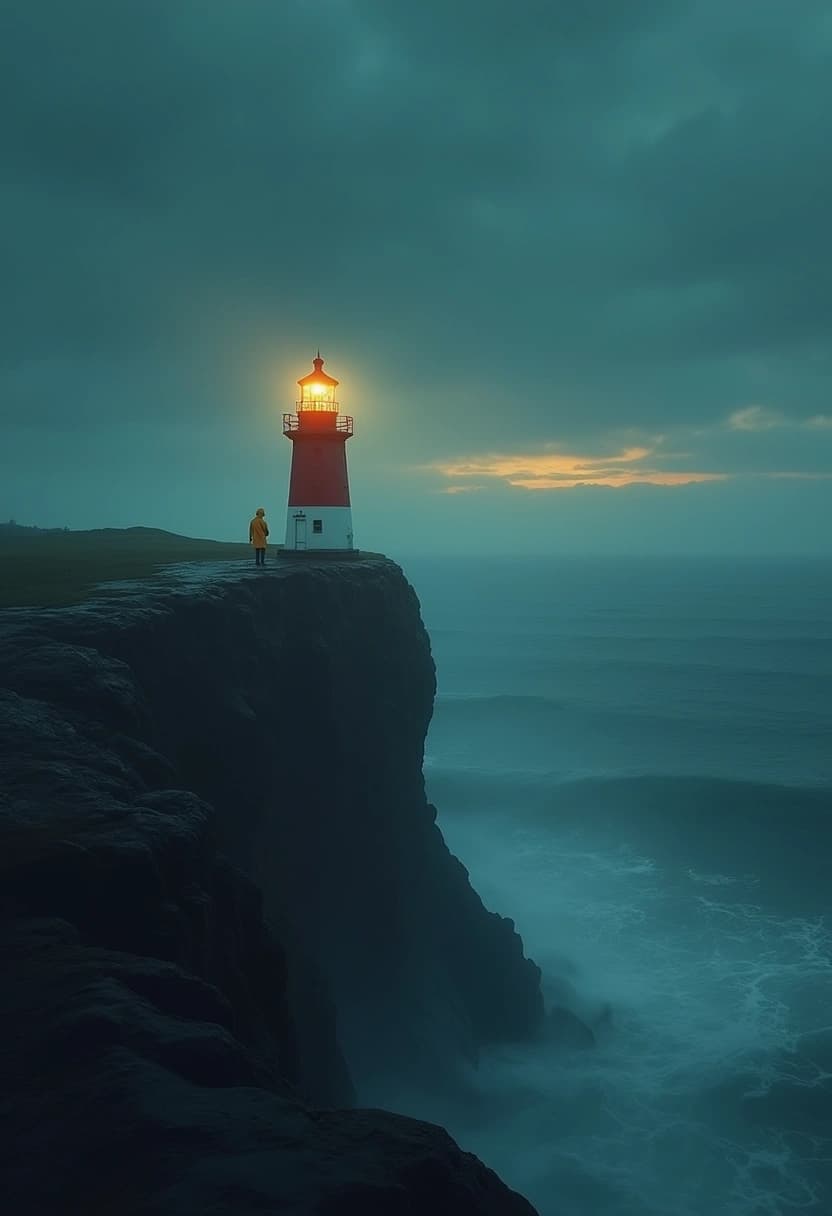
Guidance 2.5
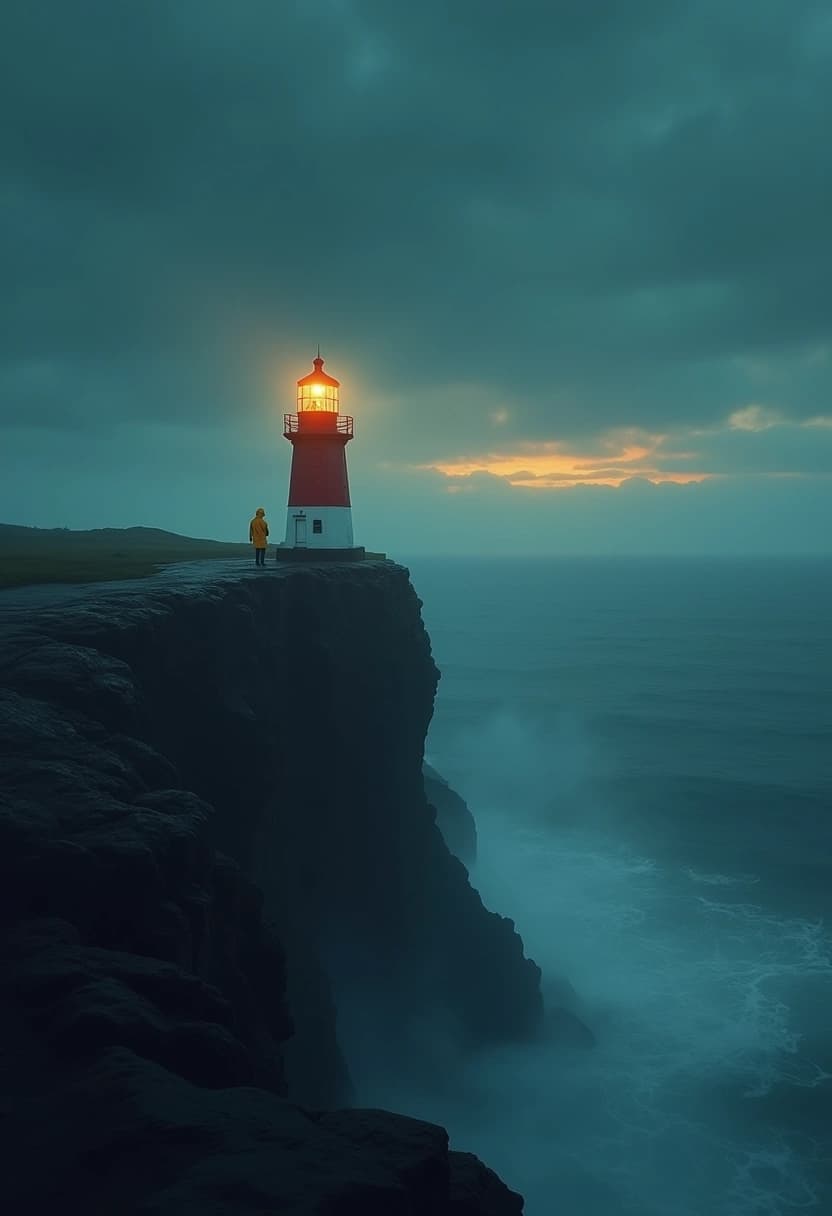
Guidance 3.0
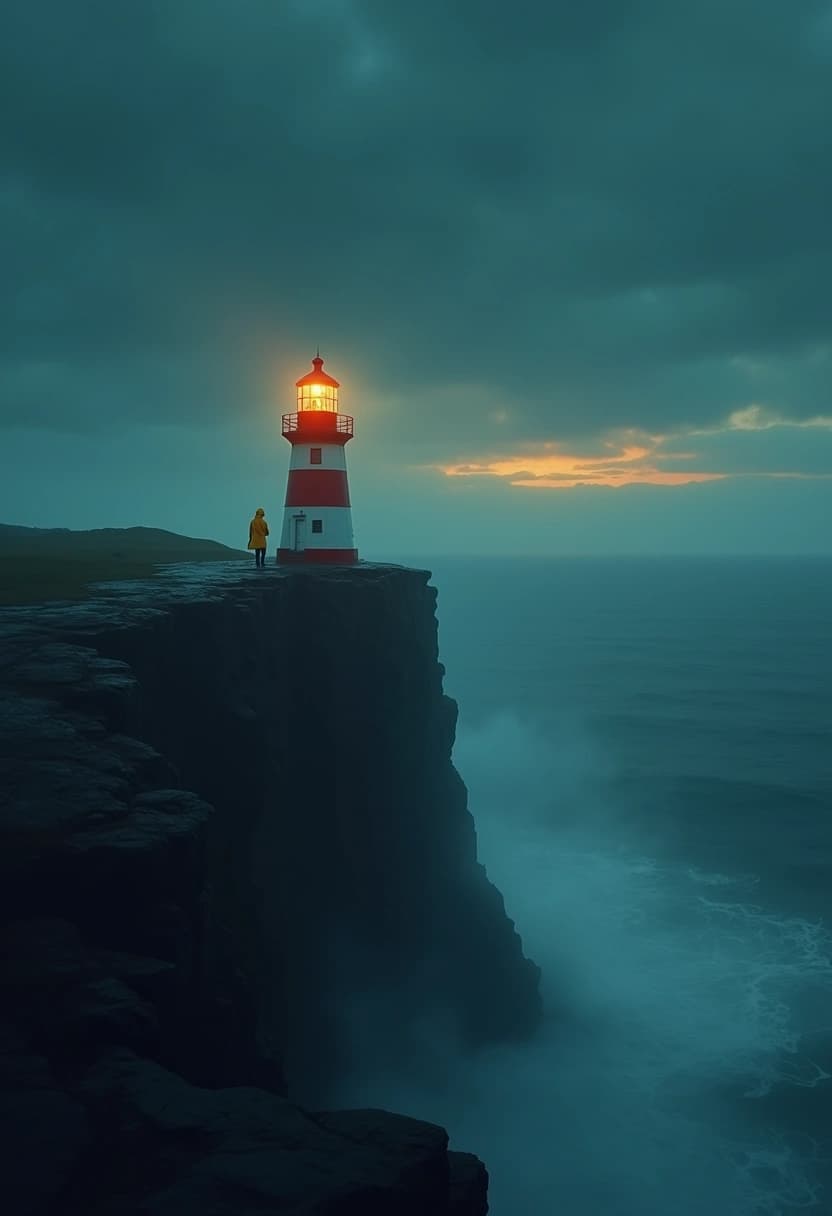
Guidance 3.5
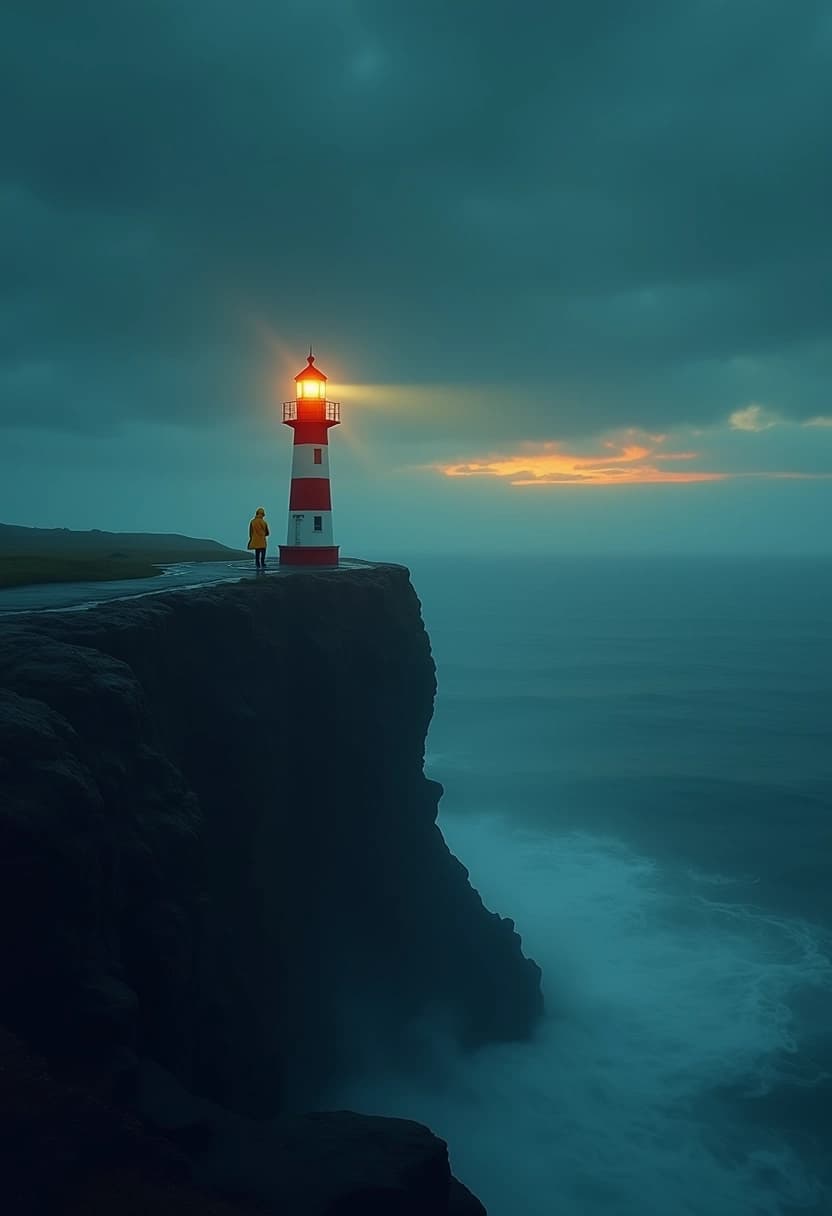
Guidance 4.0
A (fictional) client reviewed all four and approved the 3.0 version.
Nothing was regenerated for this experiment. The agent read every condition straight out of the workflow embedded in each file, not from filenames or notes. That matters: if your eval records what you think you ran rather than what you ran, the loop learns the wrong lesson.
How Does the Loop Map to Real Steps?
Here is how each step mapped to a real call:
- Run. The four renders, found as one creative session in the library.
- Inspect the trace. The embedded ComfyUI graph of each render: model, seed, steps, guidance, prompt.
- Feedback. An experiment with a stated hypothesis (“higher guidance improves literal adherence”), the four runs registered with their exact conditions, scores on three dimensions, and two head-to-head comparisons.
- Add an eval data point. A summary per condition, with the client’s approval recorded as an outcome alongside the scores.
- Change. Pick the next render’s settings from evidence rather than memory.
One rule we held to: the agent’s scores are labelled as agent scores, every time. An automated judge is a useful second opinion. It is not a substitute for the person who signs off the poster, and an eval set that blurs the two can’t tell you which one drifted.
What Did the Judge See?
Scored by the agent on a 1–5 scale for prompt adherence:
Prompt adherence by guidance (agent scores, 1–5)
| Guidance | Agent score | What changed |
|---|---|---|
| 2.5 | 3 | No beam; lighthouse reads red with a white base |
| 3.0 | 3 | Same misses; best mood and spray detail |
| 3.5 | 4 | Red-and-white stripes appear |
| 4.0 | 5 | The only version with a visible beam through the fog |
On adherence, the trend is clean: more guidance, more of the prompt shows up. The 4.0 render is the only one that contains everything the prompt asked for.
But the client chose 3.0. On coherence and composition the agent agreed with the client, scoring 3.0 highest. Head to head, 4.0 won adherence and 3.0 won the other two.
Why Is the Disagreement the Data Point?
This is where the flywheel earns its keep. The obvious reading is “the judge was wrong” or “the client was wrong.” Neither is true. The prompt asked for a beam; the client wanted a mood. Those are different goals, and a single “quality” score would have averaged them into noise.
The prompt asked for a beam. The client wanted a mood. Record both, and the next change is made on evidence.
Recorded side by side, they tell you something you can act on:
- If the brief really needs the beam, the next render starts at guidance 4.0 and works on mood some other way.
- If mood wins, the prompt should stop asking for a beam the client doesn’t value, or the judge’s rubric should weight it lower.
Either way, the next run is a change made on evidence. That is the whole point of the loop.
What Is Still Missing?
This was one turn of the flywheel, not a production system, and we want to be plain about the edges:
- One rater per dimension. A second human rater would turn “agent vs. client” into a real agreement measure. The experiment summary already reports rater counts and disagreement, so adding a person’s scores is a single step.
- The “change” step has no home yet. The winning change here was a sampler setting, not a new model version. Today there is nowhere to record “for this brief, start at guidance 4.0” so the next agent picks it up. That is the piece we are working on next.
- Four renders is a small sample. It shows the loop works. It doesn’t settle the best Flux guidance for poster key art.
See It for Yourself
The four renders, the agent’s findings and the step-by-step mapping are in a public collection: the eval flywheel gallery. Each image shows its seed, model, steps, and sampler. If you have thousands of renders of your own, the same discipline starts with keeping each render’s recipe with the render.
Key Takeaways
- The run, feedback, trace, eval, change loop works for generative media when the trace is the real workflow embedded in the file, not a note about it.
- Label automated scores as automated. Keep human judgments beside them, not merged into them.
- When the judge and the human disagree, record both: the disagreement tells you what to change.
- The weak link today is closing the loop: recording the winning change where the next run will find it.